


How Reddit, Wikipedia, and Industry Publications Influence LLM Training and Live Retrieval
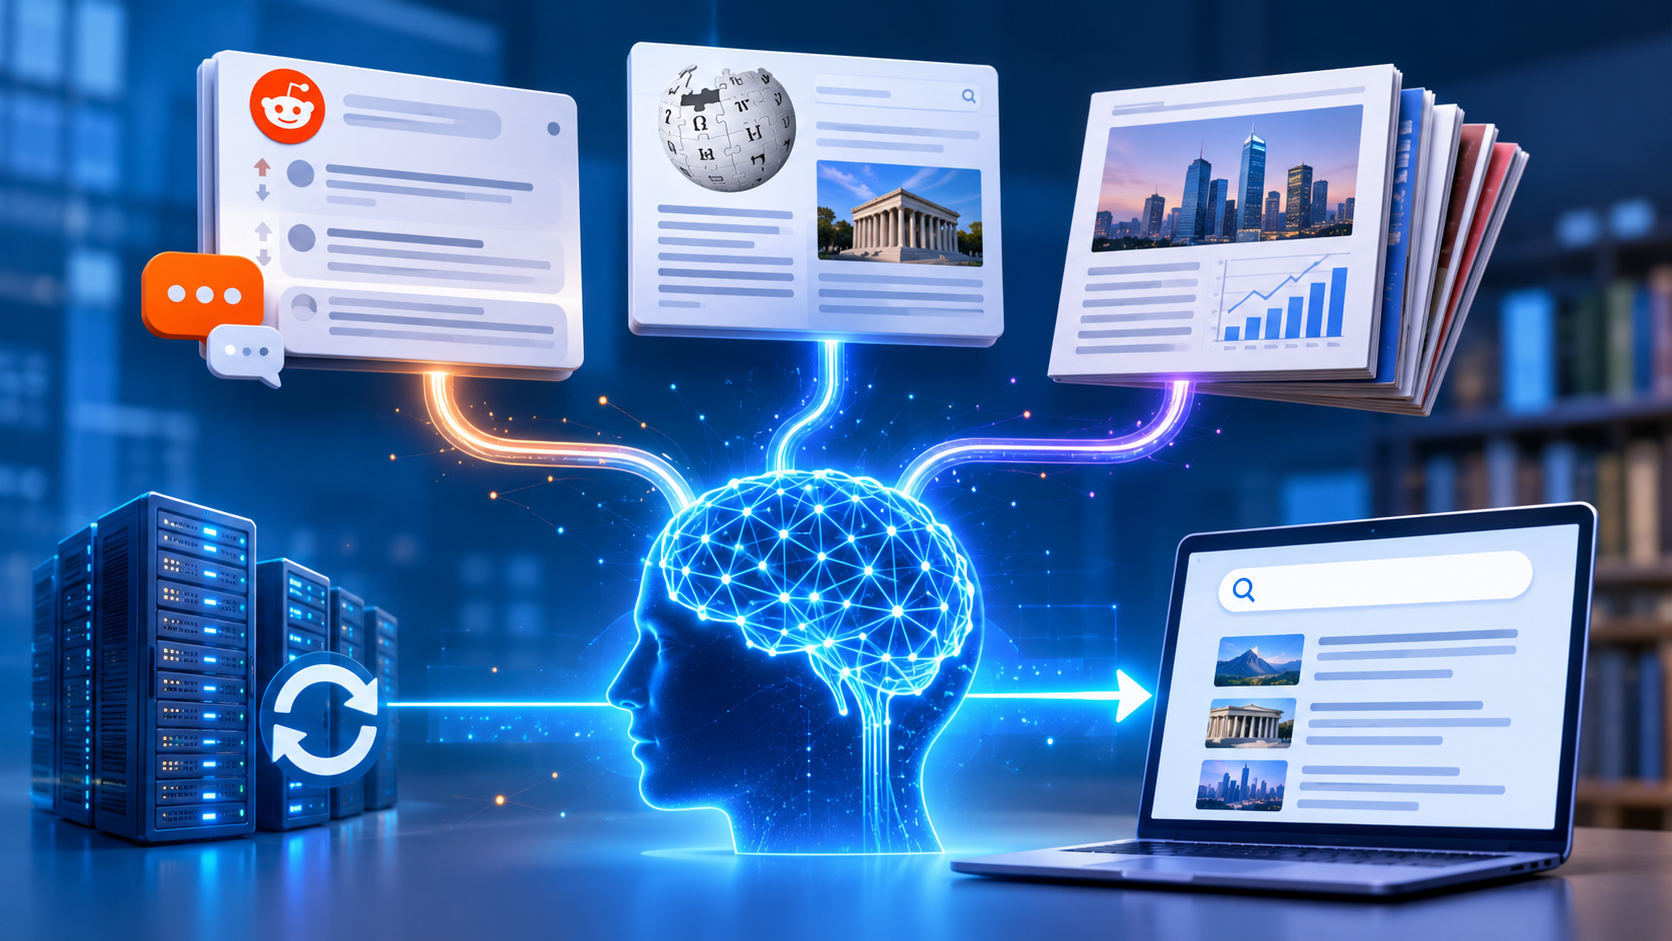
Large language models (LLMs) like ChatGPT, Gemini, Claude, and Perplexity do not form opinions out of thin air. Every answer they give is shaped by the text they learned from and, increasingly, by the web pages they fetch in real time. Three source types show up again and again in that process: Reddit discussions, Wikipedia, and industry publications.
This article explains how each one influences AI systems, why they carry so much weight, and what that means for anyone who wants their brand or expertise to appear in AI-generated answers.
Two Stages of Influence: Training vs. Live Retrieval
Before looking at each source, it helps to separate the two ways an LLM uses information.
1. Training (pretraining and fine-tuning)
During training, a model reads huge collections of text and learns patterns: facts, language, reasoning styles, and associations between topics and entities. This knowledge is "baked in" and has a cutoff date. The model does not look anything up. It simply recalls what it absorbed.
2. Live retrieval (search and RAG)
Many AI tools now search the web when answering. This is often called retrieval-augmented generation (RAG). The system runs a search, pulls in relevant pages, and writes an answer grounded in those pages, often with citations. This knowledge is fresh and can change daily.
The same website can matter in both stages, but for different reasons. Training rewards sources that are large, consistent, and widely linked. Retrieval rewards sources that are relevant, current, and easy to parse for a specific question.
Reddit: The Voice of Real People
Why Reddit matters for training
Reddit is one of the largest collections of human conversation on the internet. It covers nearly every topic, from home repair to software to local restaurants, and it is written in natural, everyday language. That makes it extremely valuable for teaching models how people actually ask questions and describe problems.
The scale of that value is visible in business deals. Reddit has signed data licensing agreements with major AI companies, including Google and OpenAI, which shows how seriously the industry treats its content as training material.
Voting also acts as a rough quality signal. Posts and comments that earn upvotes tend to be more useful, more accurate, or more relatable than those that get ignored. Some earlier training pipelines used vote counts as a filter to pick higher quality text.
Why Reddit matters for live retrieval
People often add the word "reddit" to their searches because they want honest opinions, not marketing copy. AI search tools have picked up on that behavior. When a question is about product comparisons, recommendations, or real-world experiences, retrieval systems frequently pull Reddit threads because they contain firsthand views.
Studies of AI citations have repeatedly found Reddit among the most frequently referenced domains, especially for comparison and "which one should I pick" style queries.
Strengths and risks
- Strength: Authentic language, real experiences, and diverse viewpoints.
- Strength: Fresh discussion on new products and trends.
- Risk: Misinformation, sarcasm, and outdated advice can be repeated as fact.
- Risk: Brand spam gets downvoted or removed, so promotional posts rarely help.
Wikipedia: The Backbone of Structured Knowledge
Why Wikipedia matters for training
Wikipedia has long been treated as a premium source in LLM training. It is multilingual, neutrally toned, heavily edited, and packed with citations. Its pages follow a consistent structure, which helps models learn how entities (people, companies, places, concepts) relate to each other.
Training teams have often given Wikipedia extra weight, sampling it more than once, because the quality per word is so high. The result is that models tend to know well-documented entities very well, and know poorly documented ones barely at all.
Why Wikipedia matters for live retrieval
Wikipedia pages are clean, well organized, and quick to fetch. They are a common grounding source for definitions, background facts, dates, and summaries. Knowledge graphs and search features that feed AI systems also draw on Wikipedia and its sister project Wikidata, which stores facts in structured form.
Strengths and risks
- Strength: Reliable baseline facts with sourcing.
- Strength: Strong entity definitions that help models recognize who or what something is.
- Risk: Coverage gaps. Smaller businesses and niche topics often have no page.
- Risk: Strict notability and neutrality rules mean brands cannot simply write their own entries. Conflict of interest edits are discouraged and often reverted.
Industry Publications: The Authority Layer
Why industry publications matter for training
Trade magazines, professional journals, respected news outlets, and expert blogs supply depth that forums and encyclopedias often lack. They contain original reporting, data, analysis, and specialist vocabulary. When a model learns what experts say about a field, a lot of that knowledge comes from these publications.
Several major publishers have also struck licensing partnerships with AI developers, which reflects how much value is placed on professionally edited content.
Why industry publications matter for live retrieval
When an AI system needs to answer a question that calls for credibility, such as a legal, medical, financial, or technical topic, retrieval systems lean toward sources that look authoritative. Signals can include:
- Established domain reputation and backlinks
- Clear authorship and editorial standards
- Recent publication dates and updates
- Original data, quotes, or research
- Clean structure, such as headings, summaries, and schema markup
A mention or quote in a respected industry outlet can therefore do double duty. It builds trust with human readers and gives AI systems a credible page to cite.
Strengths and risks
- Strength: Expertise, accuracy, and professional editing.
- Strength: Strong trust signals that retrieval systems favor.
- Risk: Paywalls can block crawlers and reduce visibility.
- Risk: Sponsored or thin content can dilute trust.
How the Three Sources Work Together
Each source plays a different role, and AI answers often blend all three.
- Wikipedia tells the model what something is.
- Industry publications tell the model who is credible and what experts conclude.
- Reddit tells the model what real people think and how they talk about it.
When these sources agree about a brand, product, or person, the model is more likely to mention that entity with confidence. When they conflict, or when a brand appears in only one of them, answers become vague, cautious, or leave the brand out entirely.
Why Local and Niche Businesses Should Care
AI answers are not limited to big brands. People now ask assistants for recommendations in their own city, such as which agency to hire or which service provider is trustworthy. The assistant builds its answer from the same ecosystem described above: forum mentions, authoritative coverage, and clear entity information.
This is why more companies in Tennessee are looking at SEO Services in Nashville That Win AI Citations instead of focusing only on traditional rankings. Appearing in a list of blue links is no longer enough when the answer itself is written by an AI that decides which sources to quote. Being cited means being present in the places those systems learn from and retrieve from.
Practical Steps to Improve Your Visibility in AI Answers
1. Build a presence in genuine Reddit conversations
- Join relevant subreddits and contribute helpful, non-promotional answers.
- Follow each community's rules about self-promotion.
- Encourage honest customer reviews and discussion rather than staging them.
2. Make your entity easy to recognize
- Keep your business name, address, description, and services consistent across the web.
- Use structured data (schema markup) on your site.
- If you meet notability standards, make sure facts about you are accurate and sourced. Do not write your own Wikipedia page.
3. Earn coverage in industry publications
- Pitch original data, expert commentary, and useful guides to trade outlets.
- Contribute bylined articles that show real expertise.
- Respond to journalist requests and be quotable.
4. Publish content that retrieval systems can use
- Answer questions directly near the top of the page.
- Use clear headings, short paragraphs, lists, and tables.
- Show author names, credentials, and update dates.
- Keep pages crawlable, fast, and accessible to AI crawlers where appropriate.
5. Monitor and refine
- Regularly ask AI assistants questions about your category and note which sources they cite.
- Track which competitors appear and where they are mentioned.
- Correct inaccurate information at the source whenever possible.
Common Misconceptions
"Posting more on Reddit will make AI recommend me." Not necessarily. Spammy or purely promotional posts are removed or ignored. Real helpfulness over time is what builds mentions.
"Wikipedia is the only source that matters." It is important, but it is just one input. Many brands that lack a Wikipedia page still earn citations through strong publications and community discussion.
"Training data is all that counts." Training shapes a model's baseline knowledge, but live retrieval can override or update it. Fresh, well-structured content can still win citations today.
"Once I am in the data, I am set." Models are retrained and retrieval systems change. Visibility needs ongoing maintenance.
Key Takeaways
- LLMs learn from massive text collections (training) and fetch current pages when answering (live retrieval).
- Reddit contributes authentic human opinion and everyday language, and it is a frequent citation for recommendation queries.
- Wikipedia provides structured, neutral, well-sourced facts that help models understand entities.
- Industry publications add expertise and credibility, which retrieval systems favor for high-trust questions.
- Consistent, accurate, and helpful presence across all three builds the strongest chance of being cited.
Final Thoughts
AI answers are a reflection of the web's collective voice: the community conversations on Reddit, the structured knowledge of Wikipedia, and the expert reporting of industry publications. Brands that treat these sources as places to earn trust, not places to manipulate, will be best positioned as AI search keeps growing. Focus on being genuinely useful, accurate, and well documented, and both training data and live retrieval will work in your favor over time.

 English
 Arabic
 French
 Portuguese
 Deutsch
 Turkish
 Dutch
 Italiano
 Russian
 Romaian
 Portuguese (Brazil)
 Greek